J.Gong
2025-11-26
5.86min
🚀 Week 49: Stanza for Speed-Reading - The TL;DR Tool!
The Quest for Quick Knowledge 🤓
I stumbled upon Stanza, a rather nifty tool for Natural Language Processing, and a brilliant idea immediately sparked: what if we could build a TL;DR machine for everything we read?
The human brain is lazy (don’t worry, yours too 😉). When skimming a document, if you can just grab the Subject, Verb, and Object, you often get the basic gist of the whole story.
The Problem: Game Dialogue Fatigue 🎮
This is especially crucial in video games. Let’s be honest, who hasn’t mashed the ‘Skip’ button during a lengthy dialogue sequence? 🙋♂️ We want the story, but we also want to get back to the action! The story must be transferred, but the player’s attention span is… finite.
As you can see in the classic example below, even the Zelda games had to resort to bolding key words to make sure players didn’t miss crucial hints. Smart, but can an AI do this job for us?
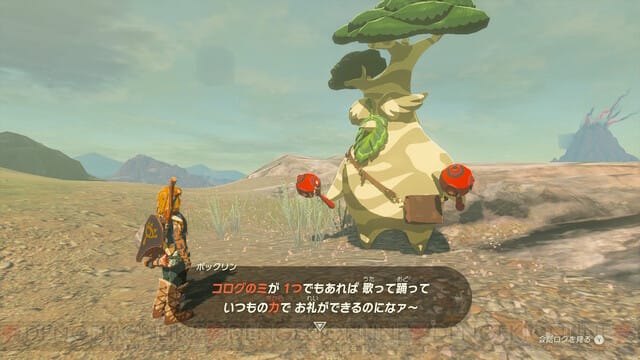
So, the big question is: Can Stanza be our robotic dialogue skipper?
Language: The Ultimate Boss Fight ⚔️
Different languages have their own unique quirks when it comes to quick reading, making this NLP quest a global challenge. I put together a notebook to test Stanza on reports about the recent Louvre Museum robbery across various languages.
🇨🇳 Chinese: The Punctuation Problem
In Chinese, there are no spaces between words! Punctuation is our only lifeline for segmentation. This makes automated fast-reading extremely difficult, as Stanza has to guess where one word ends and the next begins.
据央视新闻报道,当地时间11月25日,巴黎检察院发布公告称,围绕今年10月19日的卢浮宫盗窃案,又有四人被警方拘捕。被捕者为两名男性,分别是38岁和39岁,以及两名女性,分别为31岁和40岁,均来自巴黎地区,这些人员将接受调查人员的讯问。至此,警方锁定的4名卢浮宫劫案现场作案嫌疑人已全部归案。
🇯🇵 Japanese: The Character Clues
Japanese offers a slight advantage with its three character sets. Kanji (often nouns) and Katakana are usually the meat of the sentence, while Hiragana acts as the glue (segmenting words). You can often speed-read by just focusing on the Kanji!
【11月26日 AFP】フランスの首都パリのルーブル美術館で起きた宝飾品の盗難事件で、フランス当局は25日、容疑者4人を新たに拘束したと発表した。パリ検察は、拘束された容疑者について、パリ地域出身の38歳と39歳の男2人、31歳と40歳の女2人と説明した。この事件では、すでに4人の容疑者が拘束されている。
🇰🇷 Korean: The Space Saver
Hooray! Korean uses spaces to segment words, making it much easier for an NLP tool like Stanza to separate tokens and, thus, identify the key SOV components.
19일(현지 시각) 오전 9시 34분. 프랑스 파리에 위치한 루브르 박물관. 형광색 작업복을 입은 남성들. 사다리차를 타고 올라가 유리창을 깨고 대놓고 전시장으로 침입(侵入)해요. 그러곤 전시실에 있는 유물이 담긴 보안 유리를 이리저리 만지는데요. 박물관 관계자가 유물(遺物)을 점검하는 것 같이 보이지만, 보물을 훔친 절도(竊盜)범이었습니다.
🇹🇭 Thai: The Hardest Level 🤯
I crowned Thai the winner for “Hardest to Read.” Like Chinese, there’s no inherent spacing. Worse, the letters are often quite small, making a simple visual scan a struggle, even for the human eye.
เมื่อวันอาทิตย์ที่ 19 ต.ค. 2568 พิพิธภัณฑ์ลูฟวร์ ในกรุงปารีส ฝรั่งเศส ต้องปิดทำการเพื่อให้ตำรวจเข้าสืบสวน หลังจากผู้บุกรุกกลุ่มหนึ่งสามารถบุกเข้าไปขโมยเครื่องประดับล้ำค่าในช่วงเวลากลางวันแสกๆ นับเป็นการปล้นอุกอาจซึ่งสั่นสะเทือนพิพิธภัณฑ์ที่มีผู้เข้าชมมากที่สุดในโลกแห่งนี้
🇪🇪 🇷🇺 Estonian & Russian: The Long Noun Advantage
I used these two as comparison. They sometimes give us a helpful clue: Nouns can be quite long and are occasionally capitalized. If you know the language, these big, bold words act like signposts, making faster reading a bit easier!
«Louvre’i kuraator hindas kahju suuruseks 88 miljonit eurot ehk 102 miljonit dollarit,» ütles Pariisi prokurör Laure Beccuau, nimetades seda erakordseks summaks. Kuid tema sõnul on suurem kahju tekitatud Prantsusmaa ajaloolisele pärandile. Ta lisas, et vargad ei saa kogu summat kätte, kui neil peaks tekkima väga halb mõte need juveelid üles sulatada.
Беспрецедентный налет грабителей на Лувр, самый знаменитый музей Франции, который произошел утром в минувшее воскресенье, по своему эмоциональному воздействию на французов сравнивают с пожаром в соборе Парижской Богоматери. Действительно, люди глубоко шокированы. Заголовки СМИ пестрят: “Стране нанесена пощечина!”, “Ограбили все 68 миллионов французов”, “Франция унижена”.
The SVO Highlighter Code 🤖
Here’s the little Python bandit I used to try and steal the Subjects, Verbs, and Objects from each sentence:
def extract_and_bold_svo(doc):
    """
    Parses a Stanza document and bolds Subjects, Verbs, and Objects.
    """
    formatted_text = ""
    # These are the treasures we're looking for!
    target_deps = {'nsubj', 'nsubj:pass', 'obj', 'iobj', 'dobj'}

    for sentence in doc.sentences:
        for word in sentence.words:
            is_sub_obj = word.deprel in target_deps
            is_verb = word.upos == "VERB"

            if is_sub_obj or is_verb:
                formatted_text += f" **{word.text}**" # BOLD IT!
            else:
                formatted_text += " " + word.text # Just a filler word...

    return formatted_text
The Comedy of Errors: Where Stanza Stumbled 🤡
The results were… mixed. Stanza performed a great service, but it also showed us where the current NLP segmentation needs a serious upgrade, especially in languages without clear delimiters.
🇨🇳 Chinese Segmentation Fail
In Chinese, Stanza mistook “检察” (Prosecutor) and “院” (institution) as two separate things, when they should form the single word “检察院” (Procuratorate). Even funnier, it flagged “宫劫” (which isn’t a word) as a verb! It seems Stanza needs a better dictionary or maybe just a nap.
据 央视 新闻 报道 , 当地 时间 11 月 25 日 , 巴黎 检察 院 发布 公告 称 , 围绕 今年 10 月 19 日 的 卢浮 宫盗 窃案 , 又 有 四 人 被 警方 拘捕 。 被 捕者 为 两 名 男性 , 分别 是 38 岁 和 39 岁 , 以及 两 名 女性 , 分别 为 31 岁 和 40 岁 , 均 来 自 巴黎 地区 , 这些 人员 将 接受 调查 人员 的 讯问 。 至 此 , 警方 锁定 的 4 名 卢浮 宫劫 案 现场 作案 嫌疑 人 已 全部 归案 。
 {
      "id": 10,
      "text": "宫劫",
      "lemma": "宫劫",
      "upos": "VERB",
      "xpos": "VV",
      "head": 11,
      "deprel": "compound",
      "start_char": 133,
      "end_char": 135,
      "ner": "I-EVENT",
      "multi_ner": [
        "I-EVENT"
      ],
      "misc": "SpaceAfter=No"
},
🇰🇷 Korean: Missing the Target
프랑스(France) 파리에(Paris) 위치한(located) 루브르(Loure) 박물관(Museum)
Stanza correctly identified “위치한” (located) as a verb but then completely missed the Subject and Object for the sentence. It was like shouting “Action!” but then forgetting who the actors and the props were.
19일( 현지 시각 ) 오전 9시 34분 . 프랑스 파리에 위치한 루브르 박물관 . 형광색 작업복을 입은 남성들 . 사다리차를 타고 올라가 유리창을 깨고 대놓고 전시장으로 침입( 侵入 )해요 . 그러곤 전시실에 있는 유물이 담긴 보안 유리를 이리저리 만지는데요 . 박물관 관계자가 유물( 遺物 )을 점검하는 것 같이 보이지만 , 보물을 훔친 절도( 竊盜 ) 범이었습니다 . 4인조 도둑이 박물관을 침입하고 도주하는데까지 걸린 시간은 7분에 불과했어요 . 전시실 안에서 보물을 훔치는 데는 단 3~4분밖에 걸리지 않았습니다 . 이들이 훔쳐 간 보물은 나폴레옹 1세가 부인 마리 루이즈 황후에게 선물한 에메랄드·다이아몬드 목걸이 , 나폴레옹 3세의 부인 외제니 황후의 브로치 , 18세기 마리 아멜리 왕비와 오르탕스 왕비와 관련된 사파이어 목걸이 등 총 8점이에요 .
Japanese
【 11 月 26 日 AFP】 フランス の 首都 パリ の ルーブル 美術 館 で 起き た 宝飾 品 の 盗難 事件 で 、 フランス 当局 は 25 日 、 容疑 者 4 人 を 新た に 拘束 し た と 発表 し た 。 パリ 検察 は 、 拘束 さ れ た 容疑 者 に つい て 、 パリ 地域 出身 の 38 歳 と 39 歳 の 男 2 人 、 31 歳 と 40 歳 の 女 2 人 と 説明 し た 。 この 事件 で は 、 すでに 4 人 の 容疑 者 が 拘束 さ れ て いる 。
Thai
“พิพิธภัณฑ์(Museum) ลูฟวร์(Louvre) ใน กรุง ปารีส ฝรั่งเศส(France) ต้อง ปิด(closed) ทำ(do) การ(action)” some how correct.
เมื่อ วัน อาทิตย์ ที่ 19 ต.ค. 2568 พิพิธภัณฑ์ ลูฟวร์ ใน กรุง ปารีส ฝรั่งเศส ต้อง ปิด ทำ การ เพื่อ ให้ ตำรวจ เข้า สืบ สวน หลังจาก ผู้ บุก รุก กลุ่ม หนึ่ง สามารถ บุก เข้า ไป ขโมย เครื่อง ประดับ ล้ำ ค่า ใน ช่วง เวลา กลางวัน แสก ๆ นับ เป็น การ ปล้น อุก อาจ ซึ่ง สั่น สะเทือน พิพิธภัณฑ์ ที่ มี ผู้ เข้า ชม มาก ที่สุด ใน โลก แห่งนี้ ตอน นี้ ตำรวจ กำลัง ตาม ล่า ตัว คน ร้าย ซึ่ง บุก เข้า ไป ใน ห้อง จัด แสดง Galerie d ’Apollon ( Apollo’s Gallery ) ผ่าน ทาง หน้าต่าง ชั้น 2 หลัง จาก ที่ พิพิธภัณฑ์ เปิด ทำ การ ไม่ นาน โดย ใช้ ลิฟต์ สำหรับ ขน ย้าย เฟอร์นิเจอร์ และ ก่อ เหตุ โดย ใช้ เวลา ไม่ กี่ นาที ก่อน จะ ขี่ สกูตเตอร์ หลบ หนี ไป พร้อม อัญมณี ยุคนโป เลียน 8 ชิ้น และ ทำ ชิ้น ที่ 9 ตก เอา ไว้
Estonian
« Louvre’i kuraator hindas kahju suuruseks 88 miljonit eurot ehk 102 miljonit dollarit , » ütles Pariisi prokurör Laure Beccuau , nimetades seda erakordseks summaks . Kuid tema sõnul on suurem kahju tekitatud Prantsusmaa ajaloolisele pärandile . Ta lisas , et vargad ei saa kogu summat kätte , kui neil peaks tekkima väga halb mõte need juveelid üles sulatada .
Russian
Беспрецедентный налет грабителей на Лувр , самый знаменитый музей Франции , который произошел утром в минувшее воскресенье , по своему эмоциональному воздействию на французов сравнивают с пожаром в соборе Парижской Богоматери . Действительно , люди глубоко шокированы . Заголовки СМИ пестрят : " Стране нанесена пощечина ! " , " Ограбили все 68 миллионов французов " , " Франция унижена " .
The Takeaway: Stanza can help us speed-read by highlighting the key structural components of a sentence. However, the quality of the result is heavily dependent on the language’s structure and the underlying tokenization model. For complex languages, we still need to apply a little bit of manual, human-level adjustment.