Bolt.diy
J.Gong
2026-04-06
0.58min
Bolt.diy
🛠️ The Setup
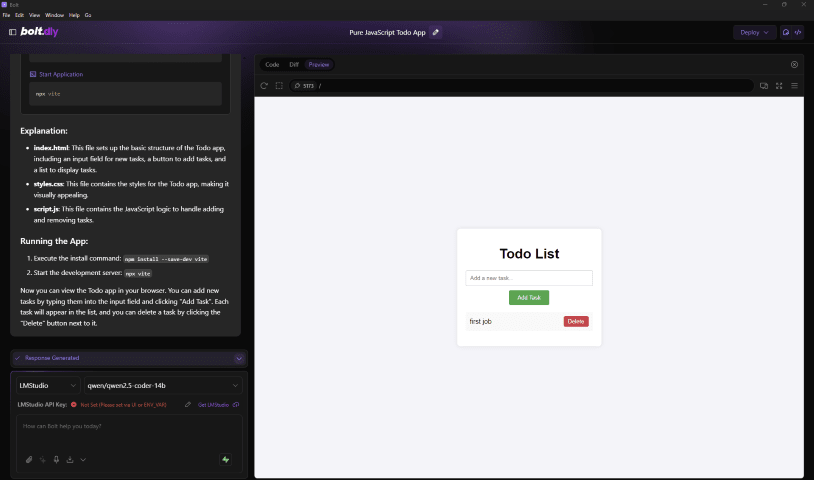
The coolest part? It can load local models. 🏠 I decided to run Qwen2.5-coder-14b (about 8GB) using LM Studio as the server.
- Context Length: 8192 🧠
- Performance: It completely maxed out my 8G GPU memory! 📈
One reason I prefer LM Studio over Ollama for this setup is the visibility—you can monitor every single token and request on the console in real-time. 🖥️🔍
📝 The Test Drive
I asked bolt.diy to build the simplest To-Do app using only pure JS, HTML, and CSS. 🎨 The generation was definitely slower compared to the online version, but honestly? It was still acceptable for a local run. 🐢➡️🐇
🏁 Final Thoughts
And there it is—a fully functional To-Do app working right in the web container! 🌐 I even tried using it as my “copilot” in OpenCode. 👨💻
While the speed isn’t quite at a “daily driver” level yet, it’s getting there. Who knows? Maybe one day this will be my go-to workflow when I’m stuck offline. ✈️🔌